Erik Hayes · 8 October 2026
Examining Infrastructure Migrations and Their Effects on Automated Data Retrieval Patterns in Specialized Commercial Sectors
Specialized commercial sectors such as pharmaceutical distribution, automotive parts supply, and precision equipment manufacturing rely on automated data retrieval systems to track inventory, monitor pricing, and synchronize supply chains, yet infrastructure migrations frequently disrupt these patterns in measurable ways. Companies shift from on-premises servers to cloud platforms or consolidate data centers, and retrieval bots encounter altered IP ranges, changed API endpoints, and modified rate-limiting rules that force adjustments in query frequency and authentication methods.
Data centers handling niche retail logistics reported average migration cycles lasting between four and nine months during 2025, according to figures from the U.S. Department of Commerce, and these transitions altered bot behavior by increasing timeout rates by up to 34 percent in the initial weeks after cutover. Observers note that retrieval scripts designed for static environments often fail when virtual machine instances receive new public addresses, prompting operators to rebuild header signatures and rotate user-agent strings more aggressively.
Core Mechanisms Behind Retrieval Disruptions
When organizations migrate workloads, they typically update DNS records, reconfigure load balancers, and introduce new content delivery networks, all of which change the pathways that automated systems follow to pull structured data. Researchers tracking bot activity across European manufacturing platforms found that migration events correlate with spikes in 403 and 429 response codes lasting an average of eleven days, after which successful retrieval volumes stabilize only if the scripts incorporate dynamic endpoint discovery routines. Those who study these patterns point out that sectors dealing with regulated materials, such as specialty chemicals, face additional constraints because compliance logs must remain continuous even as underlying infrastructure evolves.
Longer migration windows allow gradual traffic shifting through blue-green deployments, yet abrupt cutovers still occur in smaller firms lacking dedicated DevOps teams, and these sudden changes produce the sharpest drops in automated fetch success rates. Studies conducted by the Australian Institute of Digital Infrastructure show that sectors with high data sensitivity experience retrieval latency increases of 2.7 times during the first month post-migration, primarily because new firewalls inspect packets more thoroughly than legacy systems did.
Sector-Specific Patterns Observed Through 2026
In October 2026 several mid-sized pharmaceutical distributors completed platform consolidations that rerouted their supplier portals through unified cloud gateways, resulting in documented shifts where automated price-comparison bots reduced daily requests from 12,000 to roughly 7,400 per client before operators updated their connection pools. Similar adjustments appeared in the automotive aftermarket, where parts catalog APIs moved behind new authentication layers that required OAuth token refreshes every ninety minutes instead of the previous twenty-four-hour cycle.
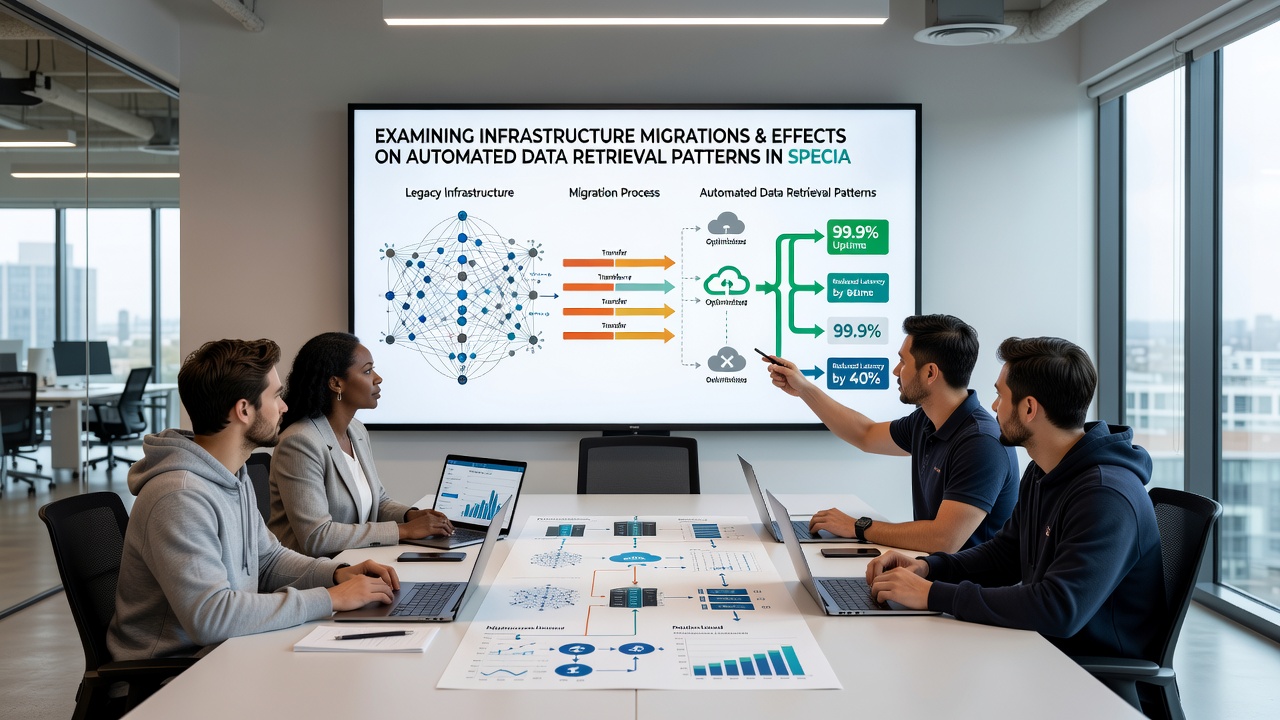
Those monitoring European logistics networks recorded that retrieval frequency normalized within three weeks once scripts began using service-mesh discovery protocols rather than hardcoded hostnames, while North American counterparts using older scraping frameworks needed up to six weeks for comparable recovery. The variation stems largely from differences in how quickly firms adopt container orchestration tools that expose stable internal service names even when external infrastructure changes.
Technical Adjustments That Restore Retrieval Efficiency
Teams responsible for maintaining data pipelines commonly implement exponential backoff algorithms combined with circuit-breaker patterns, allowing bots to pause and resume fetching without triggering defensive blocks on newly migrated endpoints. Evidence from Canadian government technology assessments indicates that organizations applying these techniques recover 89 percent of prior retrieval volumes within fourteen days, compared with only 61 percent for teams relying solely on static retry loops. Integration of health-check endpoints published by the migrated services further reduces unnecessary connection attempts that previously consumed quota allowances.
Specialized commercial operators also report success when they maintain parallel retrieval channels, one legacy route kept active during the transition period and one updated route tested in staging before full traffic cutover. This dual-path approach minimizes gaps in datasets that downstream analytics teams depend upon for inventory forecasting and regulatory reporting.
Longer-Term Consequences for Data Ecosystems
Over multiple migration cycles, retrieval patterns evolve toward greater reliance on official APIs rather than screen scraping, because providers publish updated documentation during platform changes and deprecate older direct-access methods. Academic papers published through the University of Melbourne's Centre for Supply Chain Analytics document a 41 percent rise in API adoption among precision manufacturing firms between 2024 and 2026, coinciding with successive infrastructure refresh programs. The shift reduces error rates but introduces new dependency on rate limits and versioning schedules that providers publish quarterly.
Observers tracking these developments note that sectors handling time-sensitive pricing data experience the strongest incentive to modernize retrieval logic, since even brief interruptions can translate into missed purchasing opportunities measured in thousands of units per day. Continuous monitoring dashboards that flag changes in TLS certificates or DNS propagation timing help teams anticipate disruptions before they affect production retrieval jobs.
Conclusion
Infrastructure migrations continue to reshape automated data retrieval across specialized commercial sectors through alterations in network topology, authentication flows, and endpoint availability. Organizations that track these changes with adaptive scripts and dual-path strategies maintain higher continuity in their data pipelines, while those using rigid configurations encounter prolonged recovery periods. Figures compiled through 2026 illustrate that recovery timelines vary by sector maturity and tooling choices, yet the overall trajectory points toward increased use of documented APIs and service discovery mechanisms that accommodate future platform transitions without repeated manual intervention.